
Fraud detection is a sequence of decisions with consequences for customers and investigators. A suspicious score may trigger a review, extra verification, or a declined action. Building a useful machine learning system means defining those decisions, understanding the information available at the time, and measuring the outcome after people act on it. The model matters, but so do the data pipeline, investigation tools, and feedback that surround it.
Where machine learning fits in a fraud program
A useful detection system connects a suspicious signal with a decision someone can explain and review.
Rules provide explicit responses to known conditions. Machine learning adds another way to recognize combinations of signals that deserve attention. The practical starting point is a specific workflow: assessing a payment, reviewing a new account, or prioritizing an investigation queue. Each has different timing and operational constraints.
A model should improve that workflow against a documented baseline. Define what a useful alert looks like and how much review capacity is available. More flagged activity is not automatically a better result if investigators cannot resolve it or legitimate customers encounter unnecessary interruptions.
Where fixed rules reach their limits
A fixed condition is useful when the behavior is understood and the response is clear. Problems appear when many individually ordinary signals become concerning together. Compare a model with the actual rule baseline, including the effort required to maintain both.
Recognizing combinations across a large event stream
A scoring model can evaluate several relationships in a consistent way across incoming activity. Its usefulness still depends on reliable inputs and a policy for acting on the result. Test whether the additional context improves decisions within the available response time.
Connecting detection with risk management
A fraud score belongs within a wider operating process that includes product rules, customer support, investigation, and escalation. Agree who owns each decision and which evidence must be retained. A model cannot independently establish the organization’s tolerance for loss or customer disruption.
Applications across financial products
Payments, account access, onboarding, and lending create different opportunities for detection. Select a specific journey and define what the service can observe before the decision. A result from one product should not be assumed to transfer unchanged to another.
Turn an event into a traceable decision
The model estimates risk; the surrounding policy determines what the product actually does.
The system receives an event, gathers permitted context, computes features, applies a model, and sends the score into a decision policy. That policy may combine rules, thresholds, customer checks, and review capacity. Record the versions and inputs needed to explain why a particular event received a particular outcome.
Keep model output separate from the operational action. A score describes the model's assessment; it does not itself define the right customer experience. The team still needs a response to uncertainty, missing information, an unavailable scoring service, and a person challenging an earlier decision.
Capture events with useful context
Record the event time, transaction state, relevant identifiers, and permitted context through a documented data contract. Distinguish an attempted operation from a completed one. Missing or duplicated events can distort both historical analysis and the live decision.
Turn records into reproducible features
A feature is a defined calculation rather than an informal description of behavior. Specify its window, source, handling of missing values, and update frequency. Use equivalent logic for historical training and live requests so the model sees comparable inputs.
Learn from reviewed outcomes
Create a training dataset with a clear target and an account of how each outcome was established. Keep the time of the decision separate from the time its label became known. Review unresolved and uninvestigated activity before treating it as confirmed legitimate behavior.
Calculate a score within the available time
Measure the entire request path, including feature retrieval and any external dependencies. Record the score with the model version and the policy that used it. A fast model calculation is insufficient if a slow dependency prevents the application from responding.
Route decisions into investigation
Define what happens at each relevant risk level: continue, request more verification, restrict an action, or create a review case. Include an escalation route and record the result. Investigators need context that explains the decision without requiring direct access to training systems.
Choose the fraud patterns the system will assess
Different fraud journeys need different evidence, targets, and ways to confirm an outcome.
Different forms of abuse leave different evidence. Account takeover may involve changes in access and behavior; suspicious payments involve transaction context; onboarding abuse involves identity and application information. Avoid combining all of these into one undifferentiated target simply because the outcome is called fraud.
For each workflow, define the action being protected, the available signals, and how an outcome becomes confirmed. Review those definitions with the people who investigate cases. The same event can have different interpretations depending on the service's rules, the customer's explanation, and evidence that arrives later.
Suspicious card and payment activity
Payment assessment can consider transaction context, account history, and recent changes in behavior. Distinguish a suspicious pattern from a confirmed loss. Evaluate how a policy affects legitimate customers as well as the activity the team intends to investigate.
Account access and credential misuse
A changed device or access pattern can be relevant, but it may also reflect ordinary travel or a replacement phone. Combine context carefully and provide a supported recovery route. Avoid making a single unfamiliar signal an automatic conclusion about account ownership.
Identity and application inconsistencies
Onboarding assessment depends on the information the service can lawfully obtain and verify. Define which inconsistencies merit review and which checks establish an outcome. A model’s score should support that process rather than become a substitute for identity evidence.
Abuse in lending applications
Review the relationship between application information, document checks, account activity, and later findings. Keep fraud assessment distinct from creditworthiness: they describe different questions and outcomes. Coordinate the decision with the team responsible for the lending product and its obligations.
Patterns requiring financial-crime review
Linked movements and unusual transaction sequences may be useful investigation signals. They are not, on their own, a legal determination about the activity. Route findings to the responsible specialists with the context and audit trail their review requires.
Merchant and online checkout abuse
Checkout events may involve an account, device, payment instrument, delivery information, and merchant context. Decide which relationships are relevant to the service and how they are verified. Account for product rules and ordinary shared devices before interpreting a connection as abuse.
Mobile banking and wallet activity
A mobile channel creates access, transfer, and recovery journeys with different risk decisions. Review the behavior across those journeys instead of treating each screen as an isolated event. Keep extra verification understandable and provide a safe route when customers cannot complete it.
Compare models against a useful baseline
Choose a model for the evidence and operating constraints of the actual decision, then compare it with an inspectable baseline.
Begin with an existing rule set or a simple statistical model whose behavior the team can inspect. Compare more complex approaches using the same data splits, outcome definitions, and operational measures. Keep feature and model versions tied to the result so an experiment can be reproduced.
Candidate approaches can include linear classifiers, tree-based models, anomaly scores, and relationship-based signals. Choose complexity for a reason. An improvement that depends on unavailable production data or cannot meet the decision deadline is not a deployable improvement, however strong its offline score appears.
A linear classifier as an inspectable baseline
A simple classifier can establish whether the available features contain useful information. Examine its errors and assumptions before adding complexity. Keep preparation and evaluation consistent so a later comparison reflects the candidate model rather than a different dataset.
Tree models and ensembles
Tree-based approaches can represent interactions between inputs without requiring the application to encode every combination as a separate rule. Review how missing values, rare categories, and unstable features affect the result. Evaluate the deployed calculation and its explanations alongside offline measures.
Boosted trees for structured records
Boosted tree implementations are candidates for structured transaction data. Compare their performance with simpler alternatives using the same evaluation design. Tuning should include operational limits, reproducibility, and the effort required to maintain the resulting pipeline.
Neural models for richer patterns
Neural approaches may be relevant when the problem requires sequences or other complex representations. Establish that the necessary data, skills, and serving capacity exist before choosing them. More expressive models still require meaningful labels and a useful decision policy.
Isolation and anomaly scores
An anomaly score describes how unusual an observation appears relative to a reference. That reference needs a clear definition and ongoing review. Test the resulting cases with investigators; a high anomaly score does not independently establish fraudulent intent.
Grouping activity without outcome labels
Clustering can help explore relationships or identify groups for further analysis. Its output requires interpretation and a defined downstream use. Check whether a group reflects product behavior, customer circumstances, or a data-quality issue before treating it as a detection category.
Relationship models and connected activity
Graph approaches represent links among entities such as accounts, devices, and transactions. Define each relationship and its time boundary carefully. Shared infrastructure can create legitimate connections, so investigators need access to the evidence behind a linked pattern.
Understand labeled learning and anomaly detection
Unusual activity is a reason to investigate, not proof of wrongdoing.
Supervised approaches learn from examples with recorded outcomes. Their usefulness depends on what those labels mean, how quickly they arrive, and which activity was investigated. Review that process before treating historical labels as a complete account of what happened.
Anomaly methods highlight observations that differ from an expected pattern. Scikit-learn distinguishes outlier detection on potentially contaminated training data from novelty detection on a reference dataset intended to represent normal behavior. Unusual activity is not proof of fraud; assess whether the resulting cases help investigators make better decisions.
Learning from confirmed examples
Supervised training requires a target that reflects the intended decision and a reliable process for assigning outcomes. Review label delay, investigation selection, and unresolved cases. Otherwise the model may learn the previous review policy more strongly than the underlying activity.
Exploring activity without confirmed outcomes
Unsupervised methods can identify patterns or deviations when labeled examples are scarce. Define how those findings will be reviewed and evaluated. Their value comes from useful investigations, not from the number of unusual observations they produce.
Combining limited labels with broader records
When only part of the dataset has reviewed outcomes, preserve that distinction explicitly. Compare candidate approaches against a defensible evaluation set. Avoid silently treating the unreviewed population as a large collection of confirmed legitimate examples.
Combining rules, scores, and human decisions
Rules and models can contribute different evidence to the same policy. Document their priority and interactions so the final response is reproducible. A controlled hybrid approach also gives the team a way to handle missing inputs and exceptional situations.
Use information available at decision time
The training record must represent what could have been known when the decision was made.
Build features from information the service can legitimately access when the action occurs. Document a feature's source, calculation window, freshness, and missing-value behavior. A recent-activity count needs a clear time boundary; an account characteristic needs a dependable source of truth.
Exclude information learned only after the decision from the training inputs. Otherwise evaluation can reward access to the future rather than useful prediction. Apply the same calculation rules to training and serving, and retain enough provenance to investigate a surprising score without exposing unnecessary customer information.
Amounts and activity within time windows
Define counts, totals, and timing measures relative to the event being assessed. Ensure windows exclude later information and handle retries consistently. A burst of attempted operations means something different from a burst of completed transfers.
Device and network context
Device and network signals require a documented collection purpose, reliable interpretation, and proportionate retention. Changes can help prioritize review, but shared networks and replaced devices are ordinary behavior. Evaluate combinations of context rather than assigning intent to an address.
Location and movement patterns
Location-derived features can be incomplete or imprecise. Record how the location was obtained and what level of confidence it supports. Customer travel, network routing, and product availability can explain differences that would otherwise appear unusual.
Behavior across a customer journey
Sequences such as recovery followed by a profile change and a transfer may provide more context than a single event. Define the sequence and its time boundary. Assess collection and privacy requirements before using detailed interaction or behavioral measurements.
Links among recipients and accounts
Relationship features can summarize prior interactions or shared identifiers. Keep the underlying evidence available to authorized investigators. Review legitimate shared relationships and prevent future events from leaking into the historical representation of a decision.
Historical context and its limits
Historical records help establish what was known at the time, but old behavior is not a permanent standard. Define retention, freshness, and missing-history behavior. New customers require a considered policy rather than an automatic assumption that limited history is suspicious.
Design scoring around the decision deadline
The decision deadline belongs to the product journey, not just the inference endpoint.
A live authorization flow and a next-day investigation queue require different infrastructure. Define the available response time and the consequences of delay before choosing a serving architecture. Measure the complete path, including retrieving features and applying the decision policy, rather than timing only the model calculation.
Give the service an explicit fallback for unavailable features, stale context, and scoring failures. The response should follow an agreed operational policy. Monitor how often fallbacks occur and how they affect customers, so a technically available endpoint does not conceal a degraded decision process.
A live scoring request
Specify the request schema, response, version identifiers, and timeout behavior before integration. Include enough information to connect the result with the final application action. Test the full path under realistic load and dependency failures.
Assessing risk before an operation completes
Identify the point at which the product can still pause or verify an action. Events that arrive after settlement may support investigation but cannot provide the same preventive decision. Align feature availability and scoring with that actual product state.
Protecting the authorization experience
Set an end-to-end response budget with the product team. A decision that arrives too late can create retries, uncertainty, and customer support work. Monitor latency and fallback rates together with fraud outcomes so performance problems remain visible.
Integrating payment and banking systems
Use explicit identifiers and state transitions to connect scoring with the surrounding platform. Handle retries and duplicate messages without creating inconsistent decisions. Agree what happens when the scoring service, gateway, or supporting data is temporarily unavailable.
Fit fraud signals into banking operations
A banking risk decision must fit the product’s transaction states, customer support process, and accountable review policy.
In a banking product, a risk decision can affect access to an account or the progress of a payment. Coordinate the scoring service with transaction states, support processes, and the people responsible for the product's obligations. Customers need a useful explanation and a route to resolve a problem without exposing sensitive detection details.
Separate predictive scores from generated summaries or investigator assistance. If an AI tool helps review a case, distinguish verified evidence from suggested interpretation. Keep authorization boundaries clear, and require the responsible team to approve changes that affect what the system can automatically do.
Monitoring activity in a digital banking product
Connect risk evaluation with account and transaction states so support teams can explain what happened. Review the customer journey for holds, additional verification, and recovery. Technical detection should fit a dependable operating process rather than introduce unexplained dead ends.
Supporting specialist financial-crime review
A model can help prioritize cases and assemble relevant context for qualified reviewers. Keep the responsibilities for investigation and any required reporting explicit. Preserve the evidence and decision history needed for an authorized review without exposing unnecessary personal information.
Separating application fraud from credit risk
An application can raise questions about identity, information quality, repayment ability, or several of these at once. Define separate targets and owners for those questions. A combined score can conceal which evidence and policy produced an unfavorable decision.
Protecting authentication and recovery
Access decisions should account for both suspicious activity and a legitimate customer who has lost a device or credential. Define supported verification and escalation paths. Review the complete recovery journey because it can bypass protections designed only for ordinary sign-in.
Making manual review more useful
Prioritization can help analysts spend time on cases with relevant evidence, but it must be measured against the current workflow. Track review volume, case quality, resolution time, and customer corrections. Reducing the queue is not useful if important cases disappear from view.
Build the system around data, decisions, and feedback
A production fraud service includes the data, policy, case workflow, and feedback that surround the model.
A production design needs event ingestion, feature computation, model training, controlled deployment, scoring, decision records, and investigation tools. Define interfaces between those responsibilities so the team can replace a model without silently changing the meaning of a feature or an operational action.
Capture the outcome of investigations and customer corrections through a documented feedback path. Protect access to that information and explain how it becomes eligible for future training. Keep experiment records distinct from production decision logs, while preserving the identifiers needed to connect them during an authorized investigation.
Ingest events through a stable contract
Agree schemas, identifiers, timestamps, and delivery expectations for each producing system. Detect missing or delayed inputs and retain enough operational evidence to investigate them. A model cannot compensate for an event stream whose meaning changes without notice.
Compute and serve consistent features
Keep feature definitions versioned and test historical and live calculations against the same examples. Define freshness and fallback behavior. A feature store may help organize this work, but consistency still requires deliberate data contracts and ownership.
Manage experiments and approved models
Record the training data definition, preparation code, configuration, evaluation, and approval for each candidate. Separate experimentation from permission to deploy. The team should be able to identify and restore the production version without reconstructing an analyst’s local environment.
Operate the inference service
Monitor availability, response time, input validity, and output distributions. Include the model and feature versions in decision records. Deployment checks should cover the entire inference path and a tested rollback, including compatibility with its decision policy.
Keep policy separate from prediction
A rules or decision layer translates evidence into an action under an agreed policy. Version thresholds and exceptions alongside the model. This makes it possible to investigate whether a change in outcomes came from the score, the policy, or both.
Give analysts a usable case workspace
A case needs a timeline, relevant evidence, prior actions, and a controlled way to record findings. Design access around the reviewer’s responsibilities. Avoid forcing investigators to combine screenshots and exports from multiple unrelated tools to understand one decision.
Return reviewed outcomes to the learning process
Define when a case outcome is sufficiently resolved to become a label and how corrections are handled. Preserve provenance and access controls. Feedback should improve future evaluation without silently replacing the historical record of what the service knew.
Address the limitations before scaling the model
A technically accurate score can still create an unworkable review queue or an unfair customer interruption.
Fraud outcomes may be rare, delayed, contested, or influenced by earlier review rules. New customer groups can also behave differently from the historical population. Document those limitations and test whether a model's apparent improvement remains useful across the relevant segments and later periods.
Operational capacity is another constraint. A low threshold can create more alerts than a team can investigate; a high threshold may miss activity the business wants to examine. Plan for changes in behavior, data contracts, and review workload instead of treating launch as the end of model evaluation.
Rare outcomes and representative evaluation
When the target outcome is uncommon, broad accuracy can look strong even for an unhelpful model. Preserve a meaningful evaluation population and report the measures relevant to investigation. Sampling decisions must remain documented so results can be interpreted correctly.
Customer impact from false alarms
An unnecessary restriction can interrupt a payment or lock a customer out of a service. Measure those consequences and provide an escalation route. Choose thresholds with the product and operating teams rather than optimizing a model metric in isolation.
Changing behavior after deployment
Customer activity, products, and adversarial behavior can change over time. Monitor inputs and outcomes against the conditions used in evaluation. A distribution change should trigger investigation; it does not automatically establish that immediate retraining is the correct response.
Delayed and disputed outcomes
Some events cannot be confirmed quickly and some conclusions change after further evidence. Record label availability and revisions. Evaluation should respect that timing so a recent period with unresolved cases is not presented as complete ground truth.
Explaining a decision to the right audience
Investigators, support teams, customers, and technical operators need different levels of explanation. Establish what each can access and what the evidence supports. A feature contribution is useful context, but it is not necessarily a causal explanation of a person’s behavior.
Privacy and organizational obligations
Review collection, permitted uses, retention, access, and external transfers with the responsible specialists. Apply these requirements to training copies and investigation exports as well as production records. The technical design should make those boundaries enforceable and auditable.
Attempts to manipulate detection
Treat inputs, feedback, and operating assumptions as potential points of abuse. Review who can influence labels or observe policy responses. Test failure and misuse scenarios with security specialists while keeping monitoring and recovery procedures practical for the operating team.
Measure fraud performance beyond a single accuracy number
Evaluate the model at a threshold the operating team can actually support.
Accuracy alone can hide poor performance when the cases of interest are uncommon. Review precision and recall, the confusion matrix, and the relationship between thresholds and operational outcomes. Precision concerns how many flagged cases are relevant; recall concerns how much of the labeled target activity is found. Scikit-learn documents these measures and their different purposes.
Use a later evaluation period to examine performance on activity not available during training. TimeSeriesSplit is one tool for ordered data, but the split design must also respect feature timing, label delay, and related accounts. Evaluate customer interruptions, review volume, and confirmed losses alongside model metrics before changing a production threshold.
Precision, recall, and a combined view
Precision describes the relevance of flagged examples, while recall describes coverage of the labeled target activity. Review both at the intended threshold and investigation capacity. A combined score can aid comparison, but it should not conceal which operational trade-off changed.
Comparing performance across thresholds
Curves can show how candidate thresholds change the relationship between detection and false alarms. Interpret them with the target prevalence and evaluation population in mind. Select an operating point that the product and review process can support.
Reviewing the different kinds of errors
Examine missed target events and incorrectly flagged legitimate activity separately. Their costs and remedies can differ. Investigate errors by relevant product and customer segments rather than relying only on one aggregate result.
Linking detection to financial outcomes
Define how confirmed losses, recoveries, prevented actions, and review effort are measured. Avoid treating the face value of every alert as money saved. Compare outcomes using a documented method that accounts for delays and changes in the surrounding business.
Why a high accuracy figure can mislead
A model can predict the common class very often while finding little activity worth investigating. Report the confusion matrix and decision consequences alongside headline metrics. Use a baseline that reflects the existing process and a genuinely later evaluation period.
Deliver a fraud-detection system in controlled stages
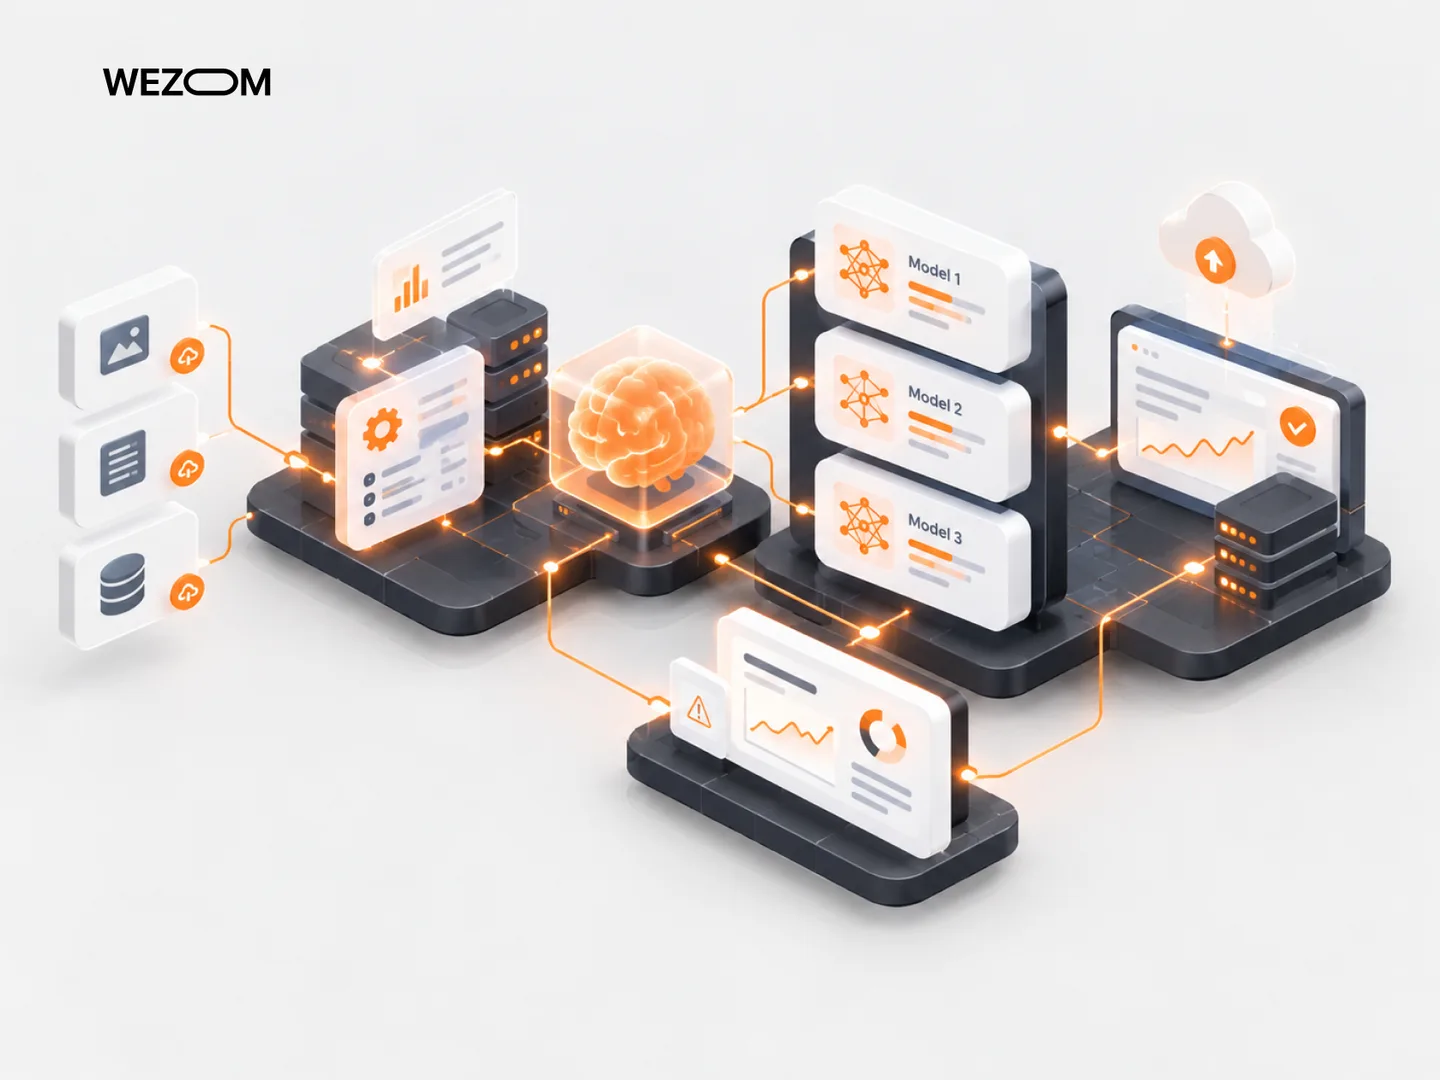
Validate the investigation and feedback workflow alongside the model before enabling customer-facing actions.
Start by agreeing the target workflow and reviewing the available data. Establish a baseline, define evaluation windows, and test whether features can be reproduced at decision time. Build the investigation and feedback process while the model is being developed rather than after alerts begin arriving.
Evaluate a candidate in a controlled mode before allowing it to affect customers. Compare its proposed decisions with the existing process, then use a staged rollout with clear monitoring and rollback criteria. Keep the authority to change thresholds or actions with named owners.
Agree the decision and its operating owner
Choose the journey to protect, the action that can follow a score, and the person accountable for the policy. Define success in terms that can be checked after rollout. Include the support and investigation teams from the start.
Audit the available historical evidence
Inventory data sources, event states, identifiers, label timing, and access constraints. Check representative records with the people who understand their origin. Resolve quality and interpretation issues before treating the dataset as a dependable training foundation.
Build features that can run in production
Implement calculations against the information available at decision time. Test historical and live equivalents, including missing inputs and new accounts. Features that work only in a prepared research extract are not ready to support an operational decision.
Train candidates against a clear baseline
Use reproducible preparation and evaluation rules for every candidate. Keep a simple approach in the comparison and document the purpose of additional complexity. Select a model based on useful evidence and operating constraints, rather than a single favorable experiment.
Validate the complete decision workflow
Review representative cases, failure scenarios, and later time periods with operating teams. Confirm that alerts contain enough evidence to resolve a case. Validation should include customer impact, review capacity, and fallback behavior as well as predictive performance.
Release scoring in controlled stages
Observe a candidate before allowing it to change customer-facing actions. Use explicit release and rollback criteria, with a named decision owner. Compare proposed and existing decisions so unexpected behavior can be investigated without immediately affecting the product.
Connect alerts with a supported review process
Make ownership, priority, escalation, and resolution states clear in the case workflow. Capture findings and corrections through structured inputs. An alerting service without a dependable investigation path leaves the most important part of the decision unfinished.
Maintain the policy and model after launch
Monitor data quality, service health, outcome measures, and review workload together. Establish a controlled process for retraining and threshold changes. A replacement must demonstrate readiness; creating a new model on a schedule is not sufficient evidence to deploy it.
Compare an internal platform with an external service
Compare complete operating workflows rather than treating a vendor score or an internal model as the whole solution.
An external product may provide useful integrations and operational tools, while an internal implementation can offer more control over features and decisions. Compare the complete workflow rather than model scores alone. Include data access, latency, investigation support, monitoring, and the ability to explain a result.
Ask how a provider handles version changes, outages, data retention, exports, and contract termination. For an internal build, identify the people who will maintain the models, pipelines, and review tools. Either approach requires accountable product and operational ownership inside the organization.
When a managed product fits
An external platform can be useful when its supported journeys, integrations, and operating tools fit the actual requirement. Test it with representative data and reviewers. Include access controls, exports, response time, and failure behavior in the evaluation.
When a tailored implementation is justified
A custom implementation may be appropriate when the decision policy, data relationships, or integration requirements are unusually specific. Identify the team that will own its lifecycle. Additional control also brings responsibility for maintenance, investigation tooling, and service reliability.
Compare the complete delivery and operating effort
Include integration, data preparation, review operations, monitoring, and change management in both options. Document assumptions about traffic and staffing. A low entry price or fast demonstration does not establish the total cost of an operating fraud process.
Plan for data access and a future exit
Review ownership, retention, portability, contract termination, and access to decision history before committing. Ask how model or policy changes are communicated. For an internal system, apply the same discipline to dependencies and the ability to restore a known working version.
Connect the investment to measurable outcomes
Measure useful service outcomes against a documented baseline; a larger alert count is not itself a business benefit.
Define the intended improvement in business terms: better investigation prioritization, fewer unnecessary customer interruptions, a more consistent decision record, or improved coverage of a defined pattern. Establish the baseline and a method for evaluating the change before rollout.
Avoid attributing every movement in a fraud metric to the model. Customer mix, product rules, review capacity, and reporting delays can all change the observed result. Review model measures and service outcomes together, and document what the available evidence can and cannot establish.
Find relevant cases sooner
A useful system presents evidence early enough for an authorized action. Measure the time from event to a usable case, not merely the speed of the model. Confirm that investigators receive the context needed to make a decision.
Reduce unnecessary customer restrictions
An improvement should help distinguish relevant activity without imposing avoidable friction on legitimate customers. Track corrections, appeals, and interrupted journeys. Review the outcome across relevant segments before assuming an aggregate improvement is beneficial everywhere.
Focus investigation effort
Prioritized queues and clearer evidence can help reviewers work more consistently. Measure case quality and resolution effort alongside queue size. The aim is a useful operating process with accountable decisions, rather than automation measured only by reduced human involvement.
Review emerging patterns systematically
A defined feedback process gives the team a way to investigate behavior not well represented in training. Combine model monitoring with investigator findings. New patterns require evidence and controlled changes rather than an assumption that a deployed model adapts on its own.
Maintain control as event volumes grow
Scaling requires dependable ingestion, feature computation, scoring, and case handling. Load-test the whole workflow and plan for review capacity. Higher technical throughput does not help if the investigation process becomes an unmanageable backlog.
Make legitimate journeys more dependable
Clear verification and recovery paths can reduce confusion when the service flags an event. Evaluate completion and support outcomes alongside detection measures. Customers should have a practical way to resolve a restriction without learning sensitive details of the detection policy.
Evaluate new capabilities without losing accountability
New techniques should strengthen the evidence and accountability of the decision process.
Relationship analysis, richer behavioral features, investigator assistance, and more automated case preparation can be candidates for improvement. Test each against a specific operational need and a clear evidence standard. A new technique should earn its place through measurable usefulness, not a claim that it makes fraud prevention autonomous.
Keep the underlying foundations dependable as the system evolves: well-defined labels, reproducible features, controlled deployments, and a way to correct decisions. Those practices let a team assess new approaches without losing the ability to explain how the production service behaves.
Assist investigators with generated summaries
A summary tool may help organize an existing evidence record, but its statements need traceable sources. Distinguish recorded facts from suggested interpretation. Keep sensitive actions and case conclusions under the authority of the responsible reviewer.
Explore relationships across connected entities
Graph analysis can reveal patterns that are difficult to see in isolated event rows. Validate the meaning of each edge and account for legitimate shared relationships. Give investigators a way to inspect the original evidence rather than relying on an unexplained network visualization.
Evaluate continuous behavioral signals carefully
Additional interaction signals may create useful context for some journeys. Assess their collection purpose, accuracy, accessibility implications, and privacy requirements. Compare their value with less intrusive alternatives before expanding what the product observes.
Consider distributed and privacy-aware learning
Distributed approaches change where training happens, but they do not automatically resolve every privacy or governance concern. Review information flows, permissions, model updates, and operational ownership. A pilot should establish both practical usefulness and the required controls.
Keep explanations useful as models evolve
Choose explanation methods and decision records that support the people responsible for the service. Test them with real investigation tasks. New capabilities should preserve the ability to reproduce a decision, identify its evidence, and correct an outcome when necessary.
FAQ
How much historical information does a fraud model need?
There is no universal record count. Assess the quality of the outcome labels, relevant variation, time coverage, and whether the data represents the intended product journey. Start with a representative evaluation and a baseline before deciding that collecting more of the same records will solve the problem.
Can a system help when confirmed fraud labels are scarce?
Anomaly and exploratory approaches can surface cases for review, but they do not independently establish fraud. Define how investigators will assess those cases and create a trustworthy outcome record. Keep unresolved examples distinct from confirmed legitimate activity.
When should a deployed model be reviewed or retrained?
Use evidence about data quality, behavior changes, delayed labels, and operational outcomes to trigger review. A calendar can organize that process, but every replacement still needs validation, approval, monitoring, and a tested rollback.
Should a model replace all existing detection rules?
Not automatically. Rules, scores, and human review can provide different kinds of control. Compare the complete policy with the existing baseline and retain explicit handling for known conditions, missing data, and exceptional situations.
How quickly can a fraud decision be returned?
The achievable response depends on feature access, dependencies, infrastructure, and the product’s decision deadline. Measure the complete path under realistic conditions. Define what the application should do when the score is delayed or unavailable.
How can a team handle unnecessary customer restrictions?
Evaluate thresholds with the product and review teams, monitor false alarms and customer corrections, and provide a supported escalation route. Investigate errors across relevant groups and journeys rather than relying only on an aggregate metric.
Is machine-learning detection appropriate for a smaller fintech product?
It can be considered when there is a clear decision, suitable evidence, and an operating team able to maintain the process. Compare simpler rules and managed options first. The appropriate approach depends on the workflow and available ownership, not company size alone.
What does a live scoring service need beyond a model?
It needs dependable event collection, reproducible features, versioned deployment, a decision policy, monitoring, failure handling, investigation tools, and a feedback process. Those responsibilities can be implemented in different ways, but each requires a clear owner.